
AI Reading
Quick summary of this article
AI Mathematics Masterclass — Chapter 19 of 48
Differentiation is the mechanical part of calculus and it takes an afternoon to learn. What takes longer is reading a derivative as information: the sign tells the optimiser which way to move, the magnitude tells it how hard to push, and the absence of a derivative tells you where a network has a corner it must handle by convention. This chapter covers the rules, when they fail to apply, and how a single derivative becomes a training signal.
1. Technical Audit & Core Learning Objectives
| Component | Common Tutorial Deficiency | Engineering Standard Applied Here |
|---|---|---|
| Rules | Listed as a table to memorise, with no worked application. | Each rule applied to an expression you will actually differentiate. |
| Existence | Differentiability assumed everywhere. | Corners and jumps drawn, with the ReLU convention explained. |
| Interpretation | “Slope” only, never connected to an optimiser. | Sign and magnitude mapped directly onto the update rule. |
| Verification | No numeric cross-check. | Central differences used to confirm every hand-derived result. |
Core learning objectives. After this chapter you should be able to:
- Apply the power, constant, sum, multiple, product, and quotient rules.
- Differentiate a polynomial and evaluate the derivative at a point.
- Explain why differentiability implies continuity but not the reverse.
- State the ReLU subgradient convention and why it is harmless.
- Read a derivative’s sign and magnitude as optimiser instructions.
- Confirm a hand-derived derivative numerically.
2. The Rules
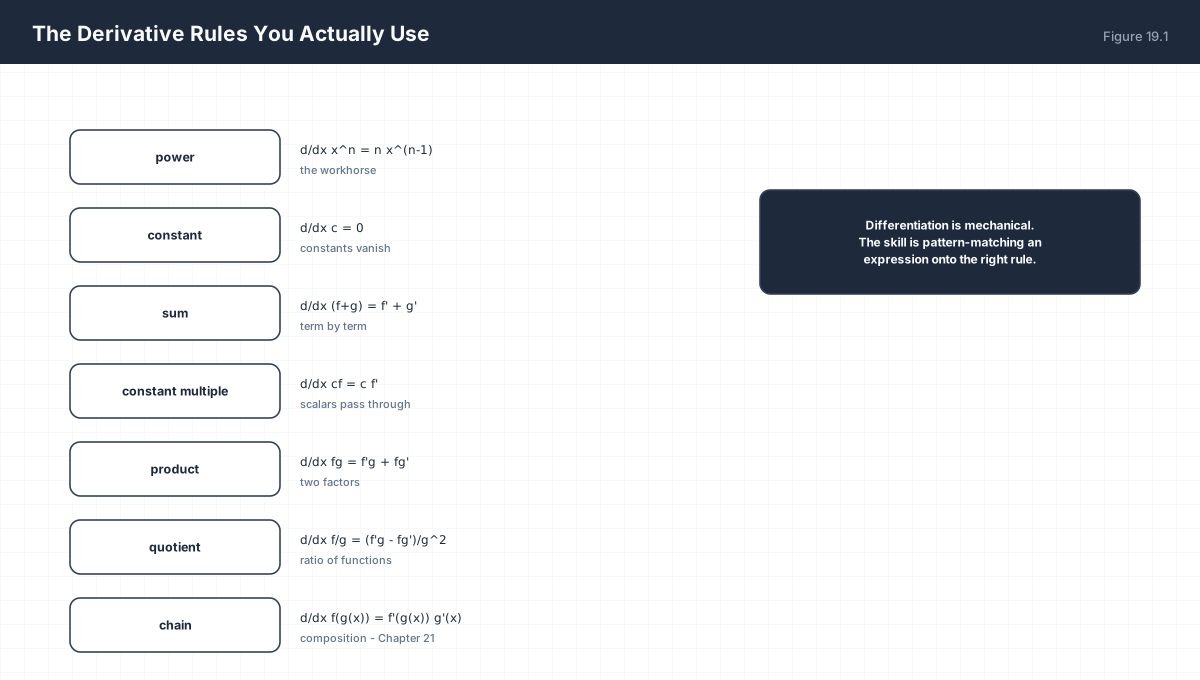
power        d/dx x^n      = n x^(n-1)
constant     d/dx c        = 0
sum          d/dx (f + g)  = f' + g'
multiple     d/dx c f      = c f'
product      d/dx (f g)    = f'g + f g'
quotient     d/dx (f / g)  = (f'g - f g') / g^2
chain        d/dx f(g(x))  = f'(g(x)) g'(x)
import numpy as np

def numeric_derivative(f, x, h=1e-6):
    return (f(x + h) - f(x - h)) / (2 * h)

# f(x) = 3x^4 - 2x + 7
f = lambda x: 3 * x ** 4 - 2 * x + 7
analytic = lambda x: 12 * x ** 3 - 2

for x in (0.0, 1.0, -2.0):
    print(f"x={x:5.1f}  analytic={analytic(x):10.4f}  numeric={numeric_derivative(f, x):10.4f}")
    assert np.isclose(analytic(x), numeric_derivative(f, x), atol=1e-4)
Every derivative you derive by hand can be checked this way. It is not rigorous, but it catches essentially every algebraic slip, and it is what torch.autograd.gradcheck automates for tensor code.
3. Recognising the Common Derivatives
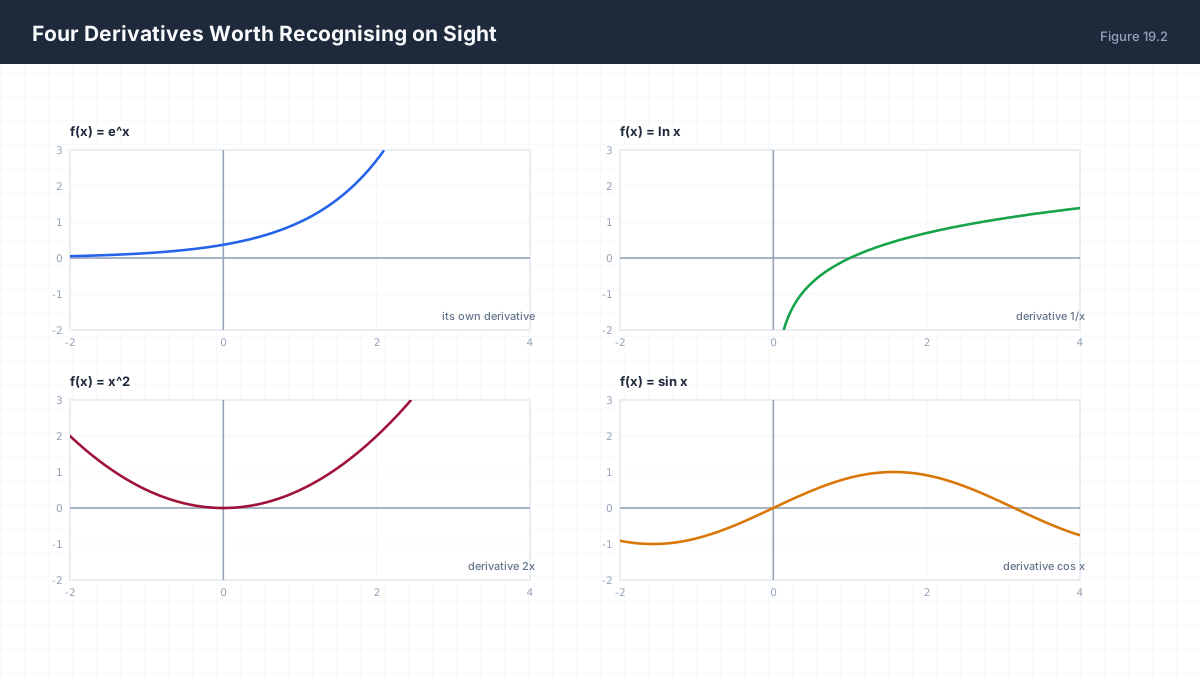
| f(x) | f'(x) | Why It Matters |
|---|---|---|
e^x |
e^x |
Its own derivative — the basis of softmax and log-space arithmetic |
ln x |
1/x |
Turns products into sums; appears in cross-entropy |
x^2 |
2x |
The shape of squared-error loss |
σ(x) |
σ(1−σ) |
Bounded by 0.25 — the vanishing-gradient source |
tanh x |
1 − tanh²x |
Bounded by 1.0, zero-centred |
import numpy as np

sig = lambda x: 1.0 / (1.0 + np.exp(-x))
sig_p = lambda x: sig(x) * (1 - sig(x))

for z in (0.0, 2.0, 6.0, 15.0):
    print(f"z={z:5.1f}  sigma={sig(z):.6f}  sigma'={sig_p(z):.3e}")
print("maximum slope of sigmoid:", sig_p(0.0))
assert np.isclose(sig_p(0.0), 0.25)
4. When a Derivative Does Not Exist
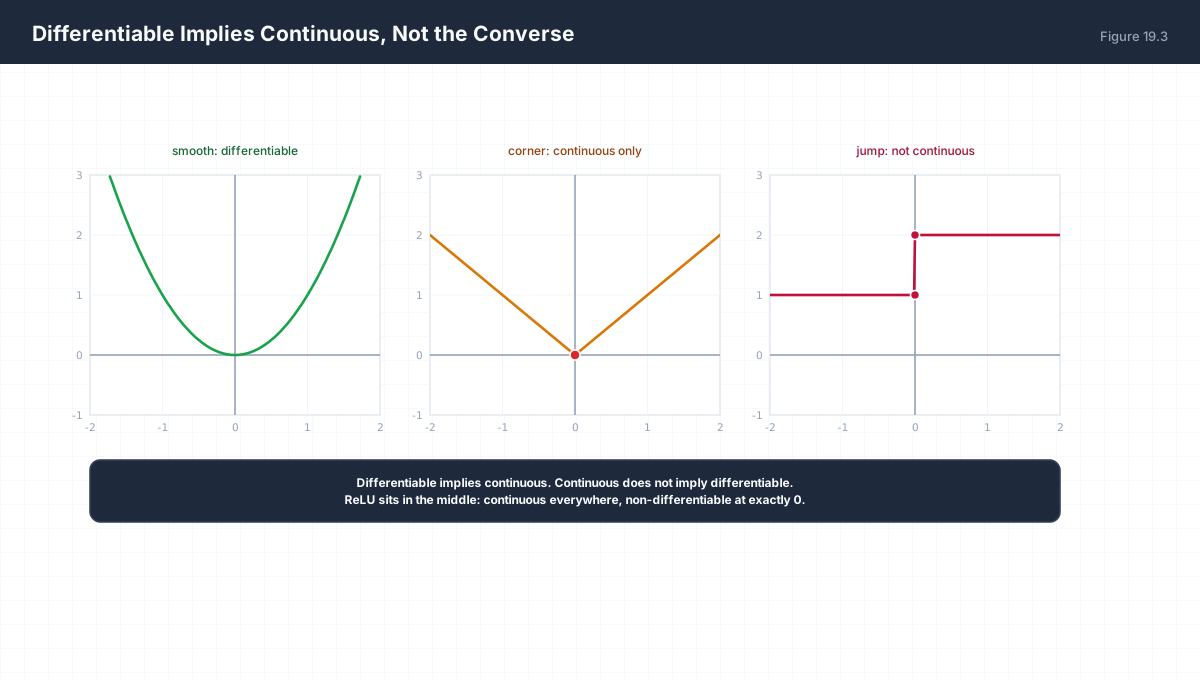
Differentiable at a  ⇒  continuous at a.
Continuous at a  does NOT imply  differentiable at a.

|x| at 0:      left slope -1, right slope +1   -> no derivative
ReLU at 0:     left slope  0, right slope  1   -> no derivative
jump at 0:     not even continuous             -> certainly not differentiable
Frameworks resolve the corner convention as follows: at exactly 0, ReLU’s derivative is taken as 0. This choice is arbitrary but harmless — any value in [0, 1] produces the same first-order behaviour, and the probability of a float landing exactly on zero in a real activation is negligible. Choosing a convention is necessary only so that the code always returns a number.
5. From Derivative to Training Signal
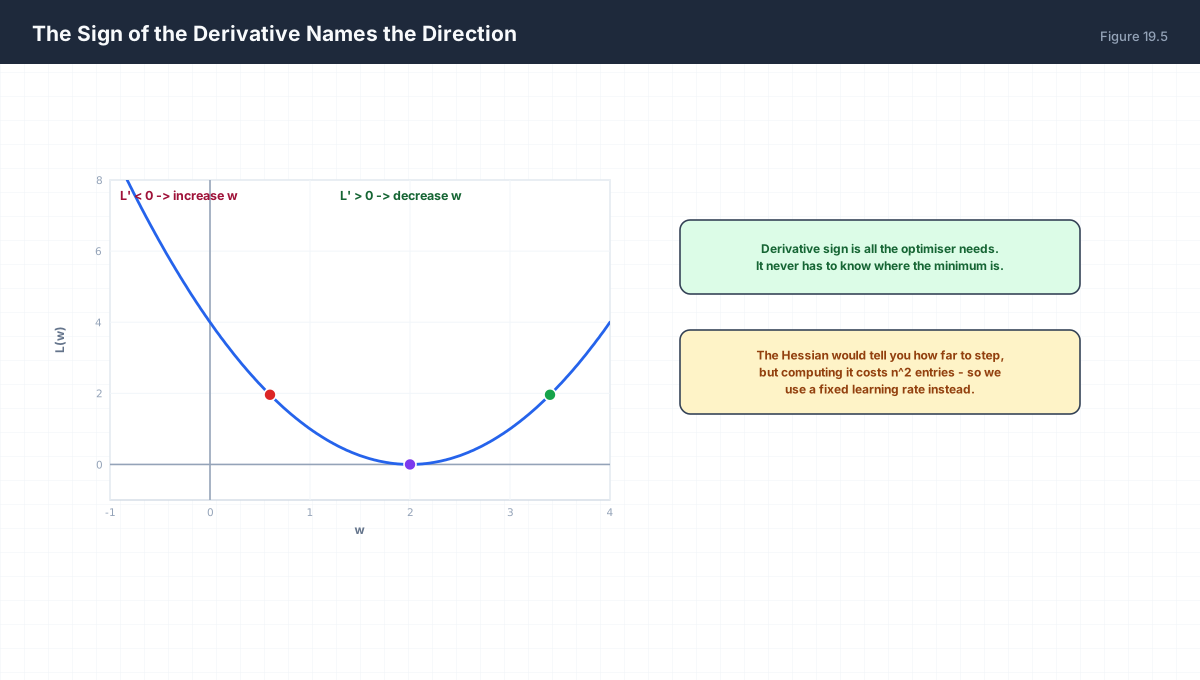
import numpy as np

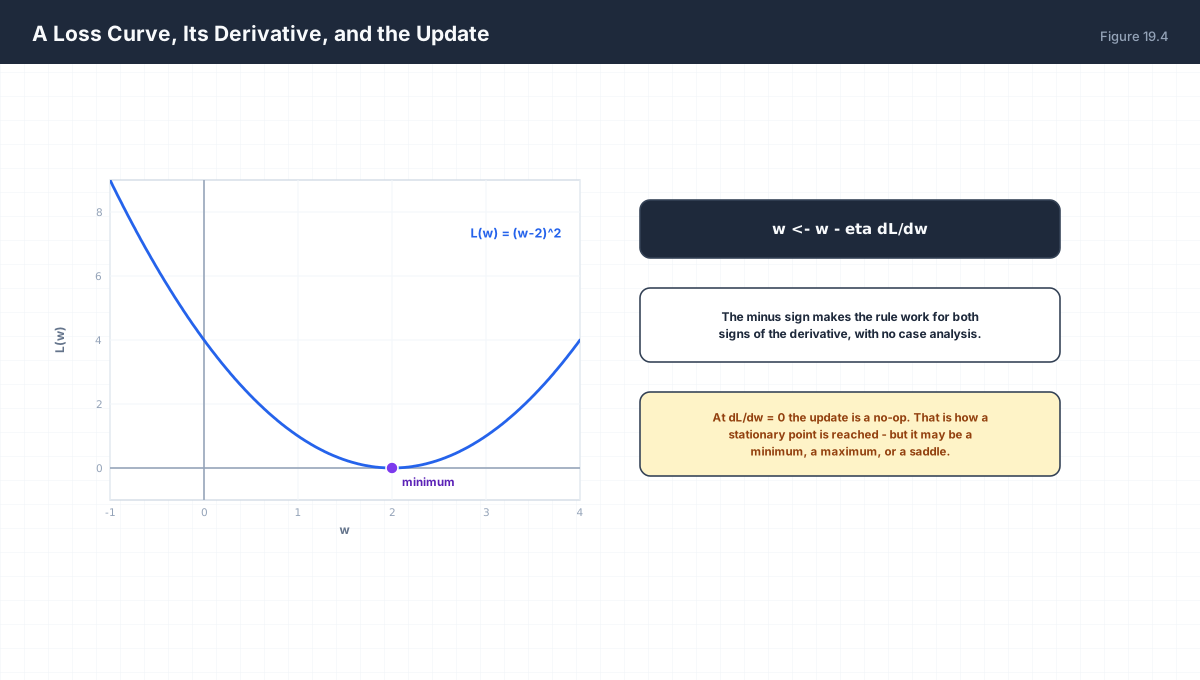
L    = lambda w: (w - 2.0) ** 2
grad = lambda w: 2.0 * (w - 2.0)

for w0 in (0.0, 1.9, 3.5):
    g = grad(w0)
    direction = "increase" if g < 0 else ("decrease" if g > 0 else "stop")
    print(f"w={w0:4.1f}  L'={g:6.2f}  -> {direction}")

# the update rule needs no case analysis
w, eta = 0.0, 0.2
for _ in range(60):                     # (1-2eta)^n shrinks the error geometrically
    w -= eta * grad(w)
print("converged w:", round(w, 9), " loss:", f"{L(w):.2e}")
assert abs(w - 2.0) < 1e-6
The single minus sign covers all three cases. That is the elegance of gradient descent: it does not need to know whether it is left or right of the minimum, only which way is downhill locally.
6. Worked Examples
6.1 Polynomial
f(x) = 5x^3 - 4x^2 + 7x - 9
f'(x) = 15x^2 - 8x + 7
f'(1) = 15 - 8 + 7 = 14
6.2 Product rule
f(x) = x^2 e^x
f'(x) = 2x e^x + x^2 e^x = x e^x (2 + x)
6.3 Quotient rule
f(x) = (x + 1)/(x - 1)
f'(x) = [(1)(x-1) - (x+1)(1)] / (x-1)^2 = -2/(x-1)^2
Always negative, so f is decreasing on each side of x = 1.
6.4 Squared error
L(w) = (w - y)^2,  y constant
dL/dw = 2(w - y)          by the chain rule with u = w - y
6.5 Why sigmoid saturates
sigma'(z) = sigma(z)(1 - sigma(z))
At z = 0:   0.5 * 0.5 = 0.25           maximum
At z = 6:   ~0.0025                    400x smaller
At z = 15:  ~3e-7                      800,000x smaller
7. Verify It in Python
import numpy as np

def nd(f, x, h=1e-6):
    return (f(x + h) - f(x - h)) / (2 * h)

# --- 1. power rule on a polynomial --------------------------------
f = lambda x: 5 * x ** 3 - 4 * x ** 2 + 7 * x - 9
fp = lambda x: 15 * x ** 2 - 8 * x + 7
assert np.isclose(fp(1), 14.0)
assert np.isclose(fp(1.7), nd(f, 1.7), atol=1e-4)
print("polynomial derivative verified at two points")

# --- 2. product rule ---------------------------------------------
g = lambda x: x ** 2 * np.exp(x)
gp = lambda x: 2 * x * np.exp(x) + x ** 2 * np.exp(x)
assert np.isclose(gp(0.8), nd(g, 0.8), atol=1e-4)
print("product rule verified")

# --- 3. quotient rule --------------------------------------------
q = lambda x: (x + 1) / (x - 1)
qp = lambda x: -2 / (x - 1) ** 2
assert np.isclose(qp(3.0), nd(q, 3.0), atol=1e-5)
print("quotient rule verified")

# --- 4. sigmoid derivative bound ---------------------------------
sig, sigp = (lambda z: 1 / (1 + np.exp(-z))), (lambda z: sig(z) * (1 - sig(z)))
assert np.isclose(sigp(0.0), 0.25)
assert sigp(15.0) < 1e-6
print("sigmoid max slope 0.25, saturated slope:", f"{sigp(15.0):.2e}")

# --- 5. ReLU subgradient convention ------------------------------
relu = lambda x: np.maximum(0.0, x)
relu_p = lambda x: float(np.asarray(x) > 0)
assert relu_p(0.0) == 0.0 and relu_p(1.0) == 1.0 and relu_p(-1.0) == 0.0
print("ReLU derivative: 0 at x=0 by convention")

# --- 6. descent converges on a quadratic -------------------------
L = lambda w: (w - 2.0) ** 2
grad = lambda w: 2 * (w - 2.0)
w, eta = 0.0, 0.2
for _ in range(90):
    w -= eta * grad(w)
assert abs(w - 2.0) < 1e-8
print("descent converged to", round(w, 8))

# --- 7. sign determines direction --------------------------------
for wv in (0.0, 4.0):
    g = grad(wv)
    moved = wv - 0.1 * g
    assert abs(moved - 2.0) < abs(wv - 2.0)      # always closer
print("update always reduces distance to the minimum")

# --- 8. derivative of a constant is zero -------------------------
assert np.isclose(nd(lambda x: 7.0, 3.0), 0.0, atol=1e-12)
print("constant derivative is zero")
print("all assertions passed")
8. Practice Questions
- Differentiate
f(x) = 4x^5 − 3x^2 + 8and evaluate atx = −1. - Apply the product rule to
x·ln xforx > 0. - Apply the quotient rule to
(2x)/(x+3)and state where it is undefined. - Show that
d/dx |x|has no value at0but is−1and+1on either side. - Why is any differentiable function continuous, and give a continuous function that is not differentiable.
- State the subgradient value frameworks use for ReLU at zero, and why the choice does not matter.
- Given
L(w) = (w−5)^2, state the sign ofL'atw = 3and the direction of the update. - Compute
σ'(4)and compare it toσ'(0); what does the ratio imply for deep sigmoid stacks? - Confirm
d/dx (x^3 − x) = 3x^2 − 1atx = 2with a central difference. - Why can a single minus sign in the update rule handle both signs of the derivative?
9. Official References & Further Reading
Continue the Course
- Course Index: AI Mathematics Masterclass — All 48 Chapters
- Previous Chapter: Chapter 18: Linear Algebra Inside Neural Networks
- Next Chapter: Chapter 20: Partial Derivatives & Gradients
- Related Series: PyTorch Engineering Masterclass — All 16 Modules