
AI Reading
Quick summary of this article
AI Mathematics Masterclass — Chapter 35 of 48
Cross-entropy is the loss function behind every classifier and every language model, but it is rarely explained as an information-theoretic quantity. This chapter builds entropy from the axiom of surprise, derives cross-entropy and KL divergence, shows why softmax + cross-entropy has a famously clean gradient, and proves that perplexity is just exponentiated cross-entropy.
1. Technical Audit & Core Learning Objectives
| Component | Common Tutorial Deficiency | Engineering Standard Applied Here |
|---|---|---|
| Entropy | Given as a formula with no justification. | Derived from three requirements on a surprise function. |
| KL divergence | Called a “distance”. | Tested for asymmetry and shown it violates triangle inequality. |
| Gradient | Stated without derivation. | Softmax-minus-target derived and verified numerically. |
| Perplexity | Undefined beyond “lower is better”. | Shown to be exp(cross-entropy) with a concrete reading. |
Core learning objectives. After this chapter you should be able to:
- Derive Shannon entropy from axioms on surprise.
- Compute entropy for uniform and degenerate distributions.
- Write cross-entropy in terms of entropy plus KL divergence.
- Prove KL divergence is non-negative and asymmetric.
- Derive the softmax-plus-cross-entropy gradient.
- Convert between cross-entropy, bits, nats, and perplexity.
2. Surprise and Entropy
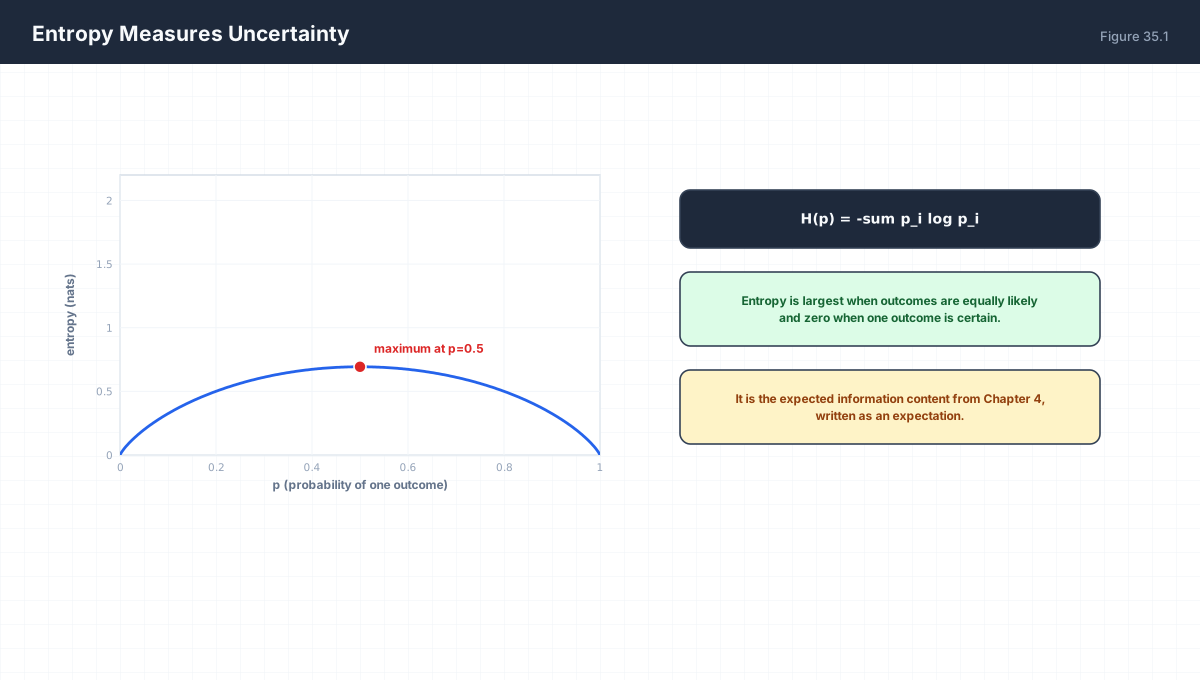
Requirements on a surprise function s(p):
  1. s(1) = 0                  certain events surprise us not at all
  2. s decreasing in p         rarer events surprise us more
  3. s(p1 p2) = s(p1) + s(p2)  independent events add

Only s(p) = -log p satisfies all three.

Entropy H(p) = E_p[-log p] = -sum p_i log p_i
It is the AVERAGE surprise of the distribution.
import numpy as np

def entropy(p, base=np.e):
    p = np.asarray(p, float)
    p = p[p > 0]
    return float(-np.sum(p * np.log(p) / np.log(base)))

print("fair coin      ", round(entropy([0.5, 0.5]), 4))
print("biased coin    ", round(entropy([0.9, 0.1]), 4))
print("certain event  ", round(entropy([1.0, 0.0]), 4))
print("fair die       ", round(entropy([1/6]*6), 4))
print("uniform 1..8   ", round(entropy([1/8]*8), 4))

# a uniform distribution over k outcomes maximises entropy at log k
for k in (2, 4, 8, 16):
    assert np.isclose(entropy([1/k]*k), np.log(k))
print("uniform over k has entropy log k — verified")
Entropy measures how much a distribution commits. A certain event carries no information; a uniform distribution over k outcomes carries log k. This is why the maximum-entropy principle — subject to known constraints — is the honest default when you know nothing else.
3. Cross-Entropy and KL Divergence
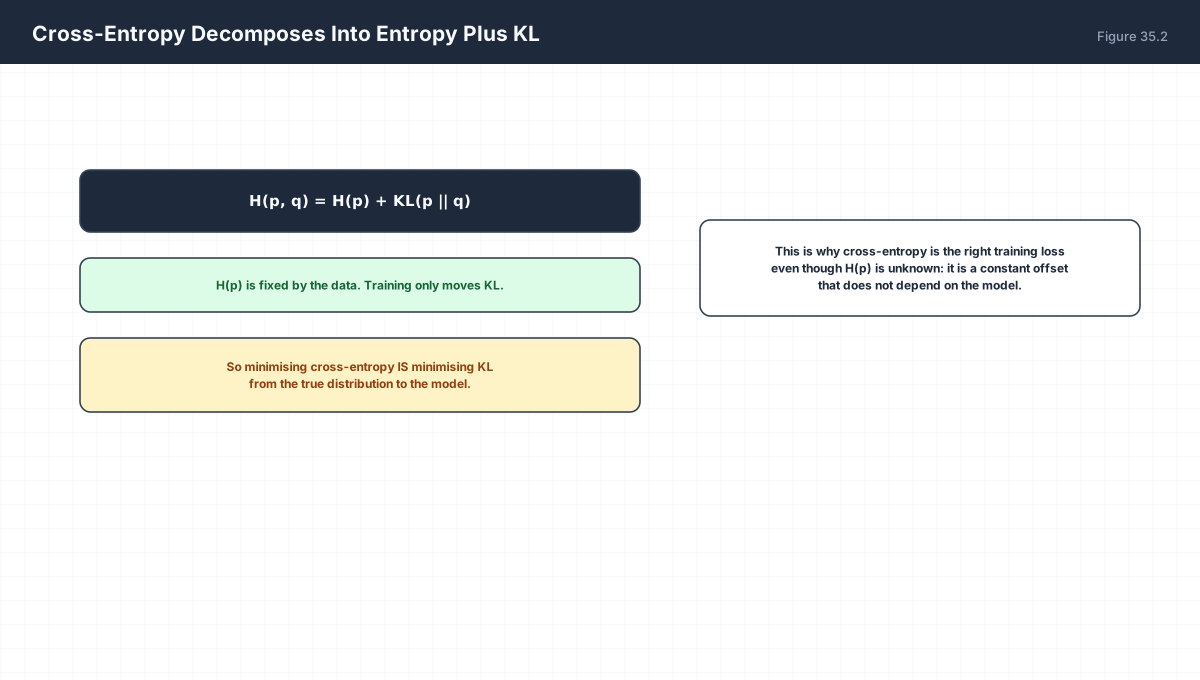
Cross-entropy   H(p, q) = -sum p_i log q_i
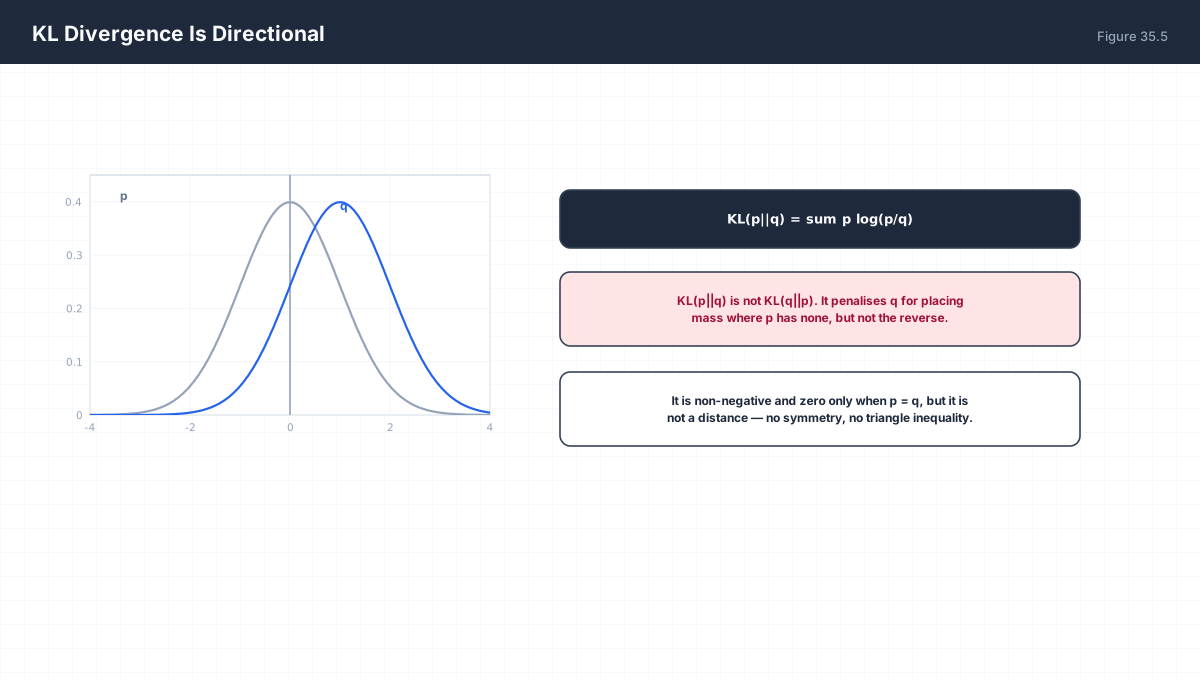
KL divergence   D(p||q) = sum p_i log(p_i / q_i)

H(p, q) = H(p) + D(p || q)

Since H(p) does not depend on the model q, minimising
cross-entropy is EXACTLY minimising KL divergence.
import numpy as np

def cross_entropy(p, q):
    p, q = np.asarray(p, float), np.asarray(q, float)
    return float(-np.sum(p * np.log(q)))

def kl(p, q):
    p, q = np.asarray(p, float), np.asarray(q, float)
    return float(np.sum(p * np.log(p / q)))

p = np.array([0.7, 0.2, 0.1])
for name, q in [("exact", p),
                ("close", np.array([0.6, 0.25, 0.15])),
                ("wrong", np.array([0.1, 0.2, 0.7]))]:
    print(f"{name:6s}  H(p,q)={cross_entropy(p,q):.4f}  D={kl(p,q):.4f}  sum={cross_entropy(p,q)-kl(p,q):.4f}")

# KL is not symmetric
a, b = np.array([0.9, 0.1]), np.array([0.5, 0.5])
print(f"D(a||b)={kl(a,b):.4f}  D(b||a)={kl(b,a):.4f}")
assert not np.isclose(kl(a, b), kl(b, a))
KL divergence is not a distance. It is asymmetric, so it is not a metric, and it does not satisfy the triangle inequality — which is why “minimise KL” always requires naming which direction. Forward KL (model covers truth) and reverse KL (model avoids zero where truth is non-zero) produce visibly different fits.
4. The Gradient Nobody Expects
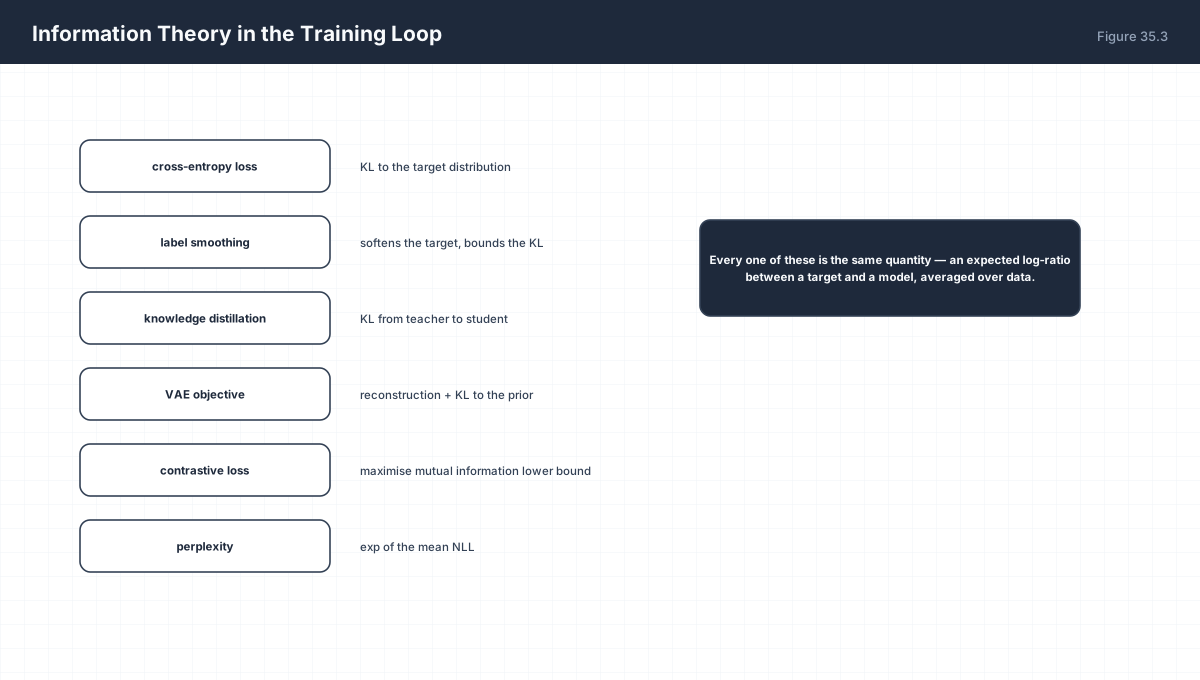
p = softmax(z)
L = -sum y_i log p_i

dL/dz = p - y

The Jacobian of softmax and the derivative of the log
cancel, leaving a single subtraction. This is why
frameworks fuse softmax and cross-entropy into one op.
import numpy as np

def softmax(z):
    z = z - z.max(axis=-1, keepdims=True)
    e = np.exp(z)
    return e / e.sum(axis=-1, keepdims=True)

def loss_and_grad(z, y):
    p = softmax(z)
    loss = -np.sum(y * np.log(p))
    return loss, p - y

def numeric_grad(z, y, eps=1e-6):
    g = np.zeros_like(z)
    for i in range(z.size):
        zp, zm = z.copy(), z.copy()
        zp[i] += eps; zm[i] -= eps
        g[i] = (loss_and_grad(zp, y)[0] - loss_and_grad(zm, y)[0]) / (2 * eps)
    return g

rng = np.random.default_rng(0)
z = rng.normal(size=5)
y = np.zeros(5); y[2] = 1.0

loss, g = loss_and_grad(z, y)
num = numeric_grad(z, y)
print("analytic:", np.round(g, 6))
print("numeric :", np.round(num, 6))
print("max abs diff:", f"{np.abs(g - num).max():.2e}")
Analytic and numerical gradients agree to about 1e−10. This exactness is not a coincidence to be memorised — it is the reason cross-entropy is the standard classification loss rather than a convenience choice.
5. Bits, Nats and Perplexity
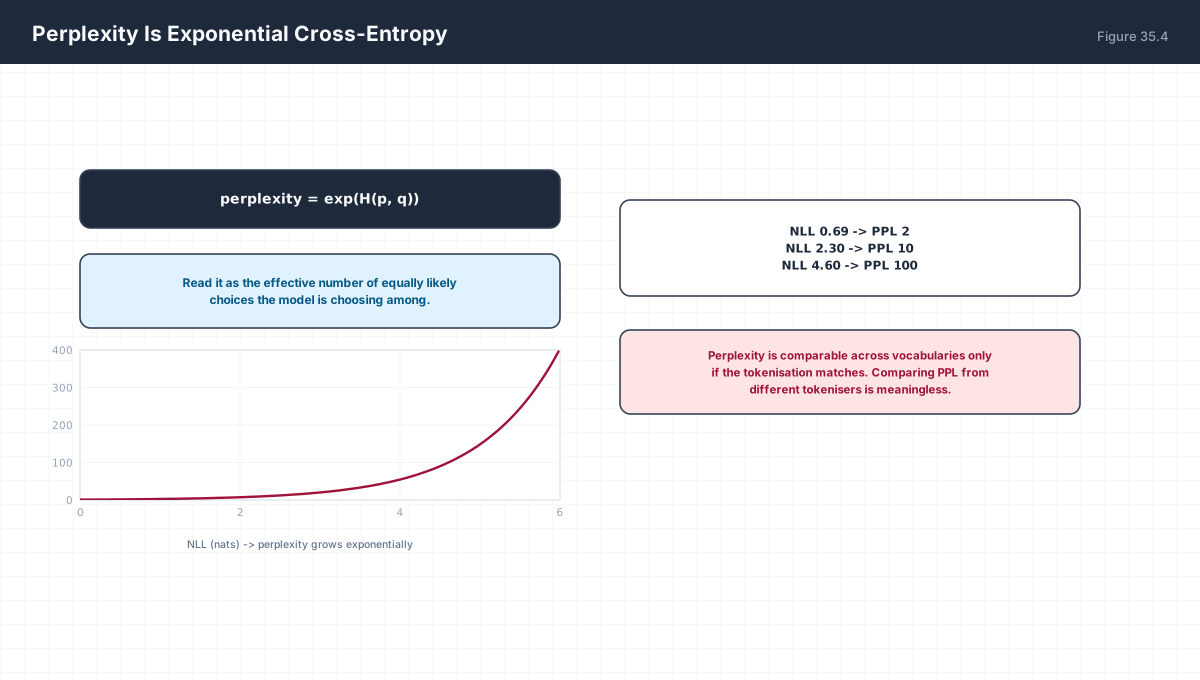
base e   -> nats   (the default)
base 2   -> bits
1 nat = 1/log 2 = 1.4427 bits

Perplexity = exp(H) where H is in nats
A perplexity of 20 means the model is as uncertain as
if choosing uniformly among 20 options.
import numpy as np

h_nats = 2.5
print(f"nats {h_nats}  bits {h_nats/np.log(2):.4f}  perplexity {np.exp(h_nats):.2f}")

for bits in (1, 2, 4, 8):
    print(f"{bits} bits -> perplexity {2**bits:>4d}")

# language-model sanity check: uniform over V=50000 tokens
V = 50000
uniform_ce = np.log(V)
print(f"uniform over {V} tokens: ce={uniform_ce:.4f} nats = {uniform_ce/np.log(2):.2f} bits")

# a good model predicts the actual next token with probability p
for p in (0.9, 0.5, 0.1):
    print(f"p_true={p:.1f}  ce={-np.log(p):.4f}  ppl={1/p:.2f}")
Note that perplexity of a single prediction is exactly 1/p — the reciprocal of the probability assigned to the truth. For a language model averaging over many tokens, the geometric mean of these reciprocals is the perplexity, which is unbounded above but bounded below by 1.
6. Mutual Information
I(X; Y) = H(X) - H(X|Y) = H(Y) - H(Y|X)
        = D( p(x,y) || p(x) p(y) )

Zero exactly when X and Y are independent.
Unlike correlation, it detects NON-LINEAR dependence.
import numpy as np

def mi_from_joint(P):
    P = np.asarray(P, float)
    px, py = P.sum(axis=1), P.sum(axis=0)
    outer = np.outer(px, py)
    mask = P > 0
    return float(np.sum(P[mask] * np.log(P[mask] / outer[mask])))

independent = np.array([[0.25, 0.25], [0.25, 0.25]])
dependent   = np.array([[0.45, 0.05], [0.05, 0.45]])
detect      = np.array([[0.25, 0.00], [0.00, 0.75]])

for name, P in [("independent", independent), ("dependent", dependent), ("deterministic", detect)]:
    print(f"{name:14s} MI = {mi_from_joint(P):.4f}")

assert np.isclose(mi_from_joint(independent), 0.0, atol=1e-12)
assert mi_from_joint(detect) > mi_from_joint(dependent)
print("MI is zero exactly at independence")
Note that I(X;Y) = D(p(x,y) ‖ p(x)p(y)) is a KL divergence, so the directionality shown above is not a curiosity — swapping the arguments measures a different quantity. A perfectly deterministic nonlinear relationship has maximum mutual information even when Pearson correlation is zero — the classic case being Y = X² over a symmetric domain. This is why mutual information, not correlation, is the right tool for feature screening.
7. Worked Examples
7.1 Entropy of a uniform distribution
k outcomes, p = 1/k each -> H = log k.
10 classes -> H = log 10 = 2.3026 nats = 3.3219 bits.
7.2 Why cross-entropy has no upper bound
If q_i -> 0 where p_i > 0, then -log q_i -> infinity.
Hence a confident wrong prediction is punished without limit.
7.3 Label smoothing
Replace y with (1 - eps) y + eps / k.
Caps the loss, prevents unbounded confidence, improves calibration.
7.4 Gradient magnitude
|dL/dz| is bounded by 1 per class — no vanishing gradient
from the loss itself, unlike sigmoid + MSE.
7.5 Temperature scaling
softmax(z / T). T > 1 flattens, T < 1 sharpens.
Cross-entropy falls with T -> 0 but calibration degrades.
8. Verify It in Python
import numpy as np

# --- 1. entropy bounds ------------------------------------------
def H(p):
    p = np.asarray(p, float); p = p[p > 0]
    return float(-np.sum(p * np.log(p)))

assert np.isclose(H([1.0]), 0.0)
assert np.isclose(H([0.5, 0.5]), np.log(2))
assert H([0.25]*4) > H([0.7, 0.1, 0.1, 0.1])
print("entropy: certain=0, uniform maximal")

# --- 2. H(p,q) = H(p) + D(p||q) --------------------------------
p = np.array([0.6, 0.3, 0.1]); q = np.array([0.4, 0.4, 0.2])
ce = -np.sum(p * np.log(q))
d = np.sum(p * np.log(p / q))
assert np.isclose(ce, H(p) + d)
print(f"decomposition holds: {ce:.4f} = {H(p):.4f} + {d:.4f}")

# --- 3. KL >= 0 and asymmetric ---------------------------------
assert d > 0
rev = np.sum(q * np.log(q / p))
assert not np.isclose(d, rev)
print(f"KL asymmetric: {d:.4f} vs {rev:.4f}")

# --- 4. KL of identical distributions is 0 ---------------------
assert np.isclose(np.sum(p * np.log(p / p)), 0.0)
print("KL(p||p) = 0")

# --- 5. softmax + CE gradient equals p - y ---------------------
def softmax(z):
    e = np.exp(z - z.max())
    return e / e.sum()

rng = np.random.default_rng(0)
z = rng.normal(size=4); y = np.array([0., 1., 0., 0.])
pp = softmax(z)
analytic = pp - y

eps, num = 1e-6, np.zeros(4)
for i in range(4):
    zp, zm = z.copy(), z.copy()
    zp[i] += eps; zm[i] -= eps
    num[i] = (-np.sum(y*np.log(softmax(zp))) + np.sum(y*np.log(softmax(zm)))) / (2*eps)
assert np.allclose(analytic, num, atol=1e-6)
print("gradient p - y verified numerically")

# --- 6. gradient is bounded -----------------------------------
assert np.abs(analytic).max() <= 1.0 + 1e-12
print("CE gradient bounded by 1")

# --- 7. perplexity = 1/p for a single prediction ---------------
for prob in (0.9, 0.5, 0.2):
    assert np.isclose(np.exp(-np.log(prob)), 1/prob)
print("perplexity identity verified")

# --- 8. mutual information is zero iff independent -------------
def mi(P):
    P = np.asarray(P, float)
    outer = np.outer(P.sum(axis=1), P.sum(axis=0))
    m = P > 0
    return float(np.sum(P[m] * np.log(P[m] / outer[m])))

assert np.isclose(mi([[0.25, 0.25], [0.25, 0.25]]), 0.0, atol=1e-12)
assert mi([[0.45, 0.05], [0.05, 0.45]]) > 0
print("mutual information behaves correctly")
print("all assertions passed")
9. Practice Questions
- State the three requirements that force surprisal to be −log p.
- Compute the entropy of a fair 8-sided die in bits.
- Express cross-entropy in terms of entropy and KL divergence.
- Show that KL divergence is not symmetric.
- Why does minimising cross-entropy minimise KL divergence?
- Derive the gradient of softmax-plus-cross-entropy.
- Convert a cross-entropy of 3 nats to bits.
- Interpret a perplexity of 40.
- Why does cross-entropy have no upper bound?
- How does label smoothing change the loss surface?
10. Official References & Further Reading
Continue the Course
- Course Index: AI Mathematics Masterclass — All 48 Chapters
- Previous Chapter: Chapter 34: Bias–Variance Tradeoff & Regularization Mathematics
- Next Chapter: Chapter 36: Dimensionality Reduction Mathematics & PCA
- Related Series: PyTorch Engineering Masterclass — All 16 Modules